


Data Engineering & ETL Pipeline Development
Turn scattered, messy data into clean, scalable, and reliable pipelines that transform raw data into trusted, business-ready insights.
Most businesses collect data across multiple systems, but it often remains scattered, inconsistent, and difficult to use. We design and build end-to-end, high-performance ETL and ELT pipelines that extract data from databases, APIs, files, and web portals, clean and transform it, and deliver structured datasets ready for reporting, Power BI dashboards, and advanced analytics. By implementing automated data flows and a structured Medallion architecture, we eliminate manual work, protect original raw data, and provide a single, reliable source of truth for your business.
We begin every data engineering project by understanding your business requirements, data sources, data flows, reporting needs, and existing technology environment. Our team designs a scalable data architecture that supports reliable data movement, transformation, quality, and analytics.
We build end-to-end ETL and ELT pipelines using Python, SQL, Azure Data Factory, and modern cloud data platforms. Our solutions integrate data from databases, APIs, files, applications, and other business systems into centralized data warehouses and data lakes.
Data quality and reliability are embedded throughout the data pipeline. We implement data validation, transformation, cleansing, error handling, monitoring, and performance optimization to ensure that downstream analytics and reporting are based on accurate and consistent data.
We also design modern data architectures using structured data layers such as Bronze, Silver, and Gold. Raw data is ingested into the Bronze layer, cleaned and validated in the Silver layer, and transformed into business-ready datasets in the Gold layer for analytics, dashboards, machine learning, and business intelligence.
From data ingestion and pipeline development to transformation, data warehousing, deployment, and optimization, we deliver maintainable, scalable, and cloud-ready data engineering solutions. Whether you are modernizing an existing data platform or building a new analytics environment, our services provide a reliable foundation for data-driven growth.
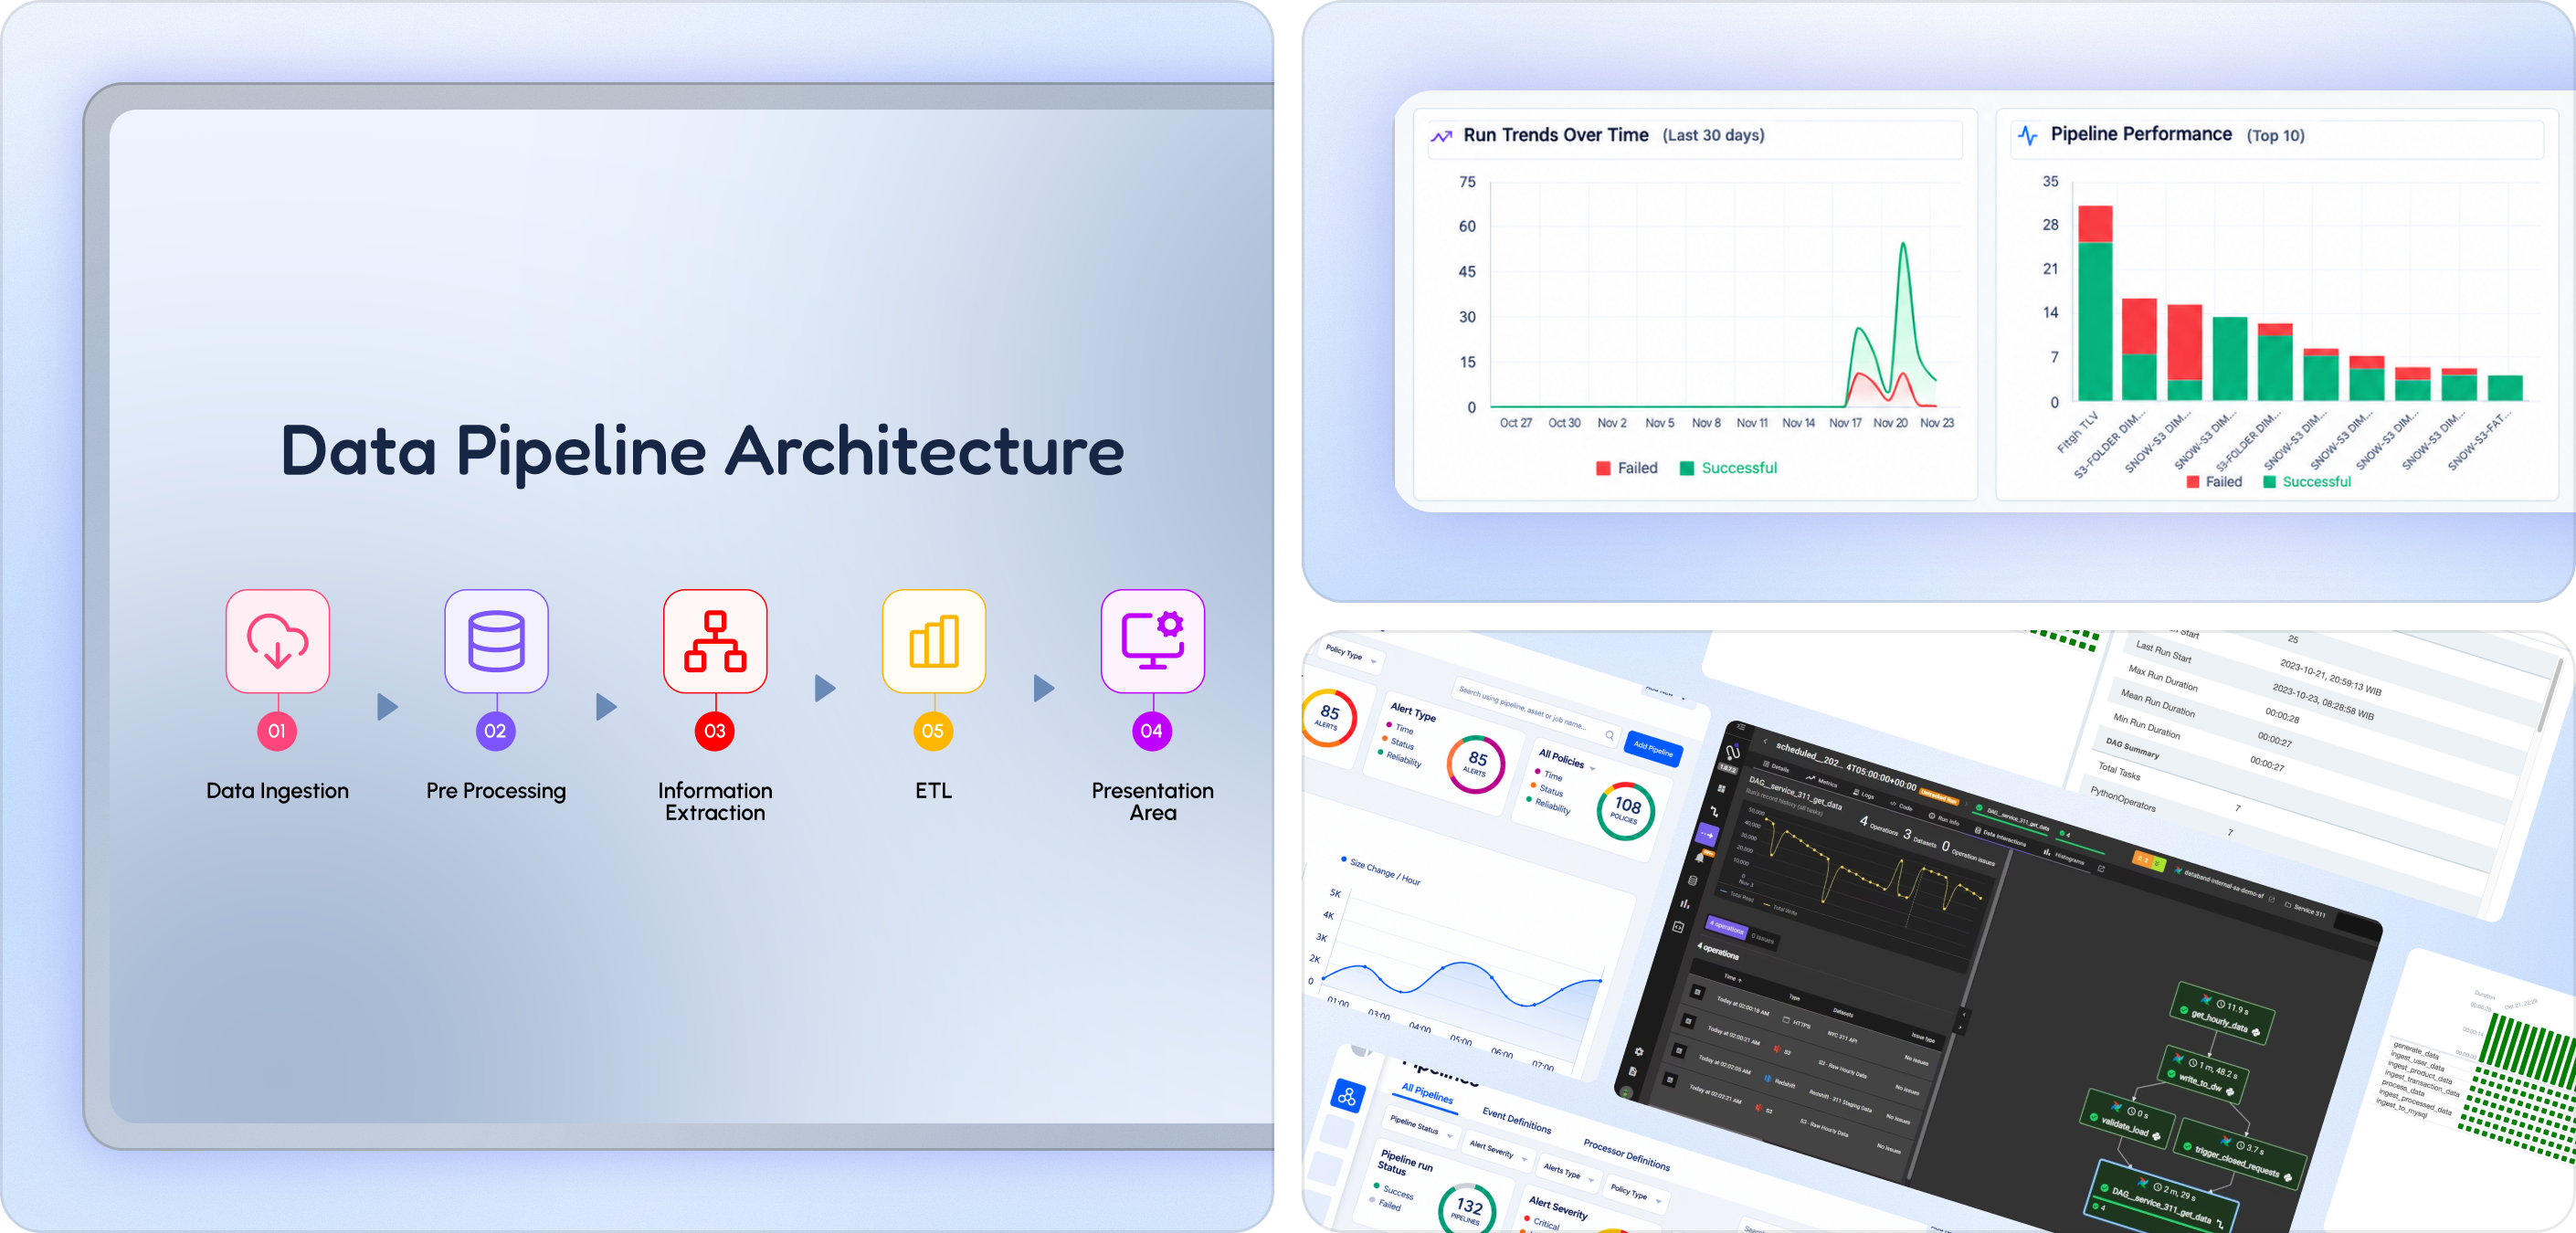
- ETL & ELT Pipeline Development : Automated pipelines that extract, transform, and load data from diverse sources into centralized platforms.
- Automated Data Ingestion : Direct extraction from web scraping, APIs, databases, flat files, and enterprise applications.
- Medallion Architecture (Bronze, Silver, Gold) : Structured data organization preserving raw data (Bronze), validating/cleansing (Silver), and delivering curated tables (Gold).
- CI/CD & Version Control : Maintainable pipeline configurations integrated with Git and continuous delivery workflows.
- Cloud Data Warehousing & Lakes : Scalable infrastructure built on Azure Data Factory, Azure Blob Storage, and Snowflake.
- Data Quality & Validation : Automated error handling, reconciliation, cleansing, and consistency checks to catch errors early.
- Python & SQL Engineering : Robust Python and SQL scripting for custom processing, complex transformations, and task automation.
- Pipeline Monitoring & Optimization : Scheduling, troubleshooting, and continuous performance tuning so data stays fresh automatically.


