


Get in touch
Work location
B-810/811, World Trade Tower (WTT), Makarba, Sarkhej Gandhinagar Highway, Ahmedabad,
Gujarat, India, 380015

Social link

ResumeFlow turns an unstructured resume PDF into a structured candidate record in seconds: contact details, education, work history and skills, all mapped onto one fixed schema.
It was built end to end by the Amilek team, from webhook intake through the extraction, review and sync layer that writes clean records straight into the tools a hiring team already runs on. Recruiters get consistent, screening-ready candidate data the moment a resume comes in.

Reading every resume by hand to extract contact details, education and experience was slow and inconsistent. Each layout is different, and fields like LinkedIn URLs, often hidden inside styled or linked text, were regularly missed or miscopied, leaving a candidate sheet full of gaps.

An AI automation takes a resume from upload to a structured record against a fixed schema, with no manual copying. Extraction fills the same six fields every run, hyperlinks are recovered from styled text, and validation flags anything incomplete before it syncs.
Every resume has its own layout, so the same six facts came out in a different order, under different headings, and sometimes not at all. In ResumeFlow, an uploaded PDF comes in through a webhook, has its text and embedded links extracted, and is passed to an LLM with a fixed JSON schema: name, email, LinkedIn, education, work experience and skills. The model fills the schema rather than deciding its own output shape, so every candidate record lands in the same form and goes straight into Google Sheets or an ATS with no re-entry.
Every resume moves through five stages before it reaches a recruiter. Splitting the pipeline this way means a single awkward resume fails in one identifiable place instead of quietly producing a half-filled record, and anything uncertain is held for a person to confirm.

Accepts a resume PDF uploaded anywhere in the hiring flow and fires the pipeline immediately, with no manual handoff or batch window.

Pulls raw text out of varied layouts, including scanned pages, and preserves embedded hyperlinks so details carried by a link survive.
Passes the text to an LLM against a fixed JSON schema, so the model fills known fields rather than inventing its own structure.
Checks required fields, normalises dates and job titles, and holds anything incomplete or ambiguous for a human to confirm.
Writes the approved record into Google Sheets or an existing ATS or CRM, so screening starts on the same data and nobody re-keys anything.

A resume uploaded anywhere in the hiring flow starts the pipeline instantly, while the recruiter is still looking at the application.

Text and OCR extraction handle multi-column layouts, tables and scanned pages, so no candidate is penalised for an unusual template.

Gemini receives the target JSON schema up front and fills it field by field, keeping output identical across thousands of documents.

LinkedIn and portfolio URLs are read from the document’s embedded links, recovering the field most often lost in manual screening.

Required fields are checked and values normalised before sync. Anything incomplete is held for review, not written through as a gap.

Finished records flow into Google Sheets, the ATS or the CRM recruiters already work in, so data lands where decisions are made.

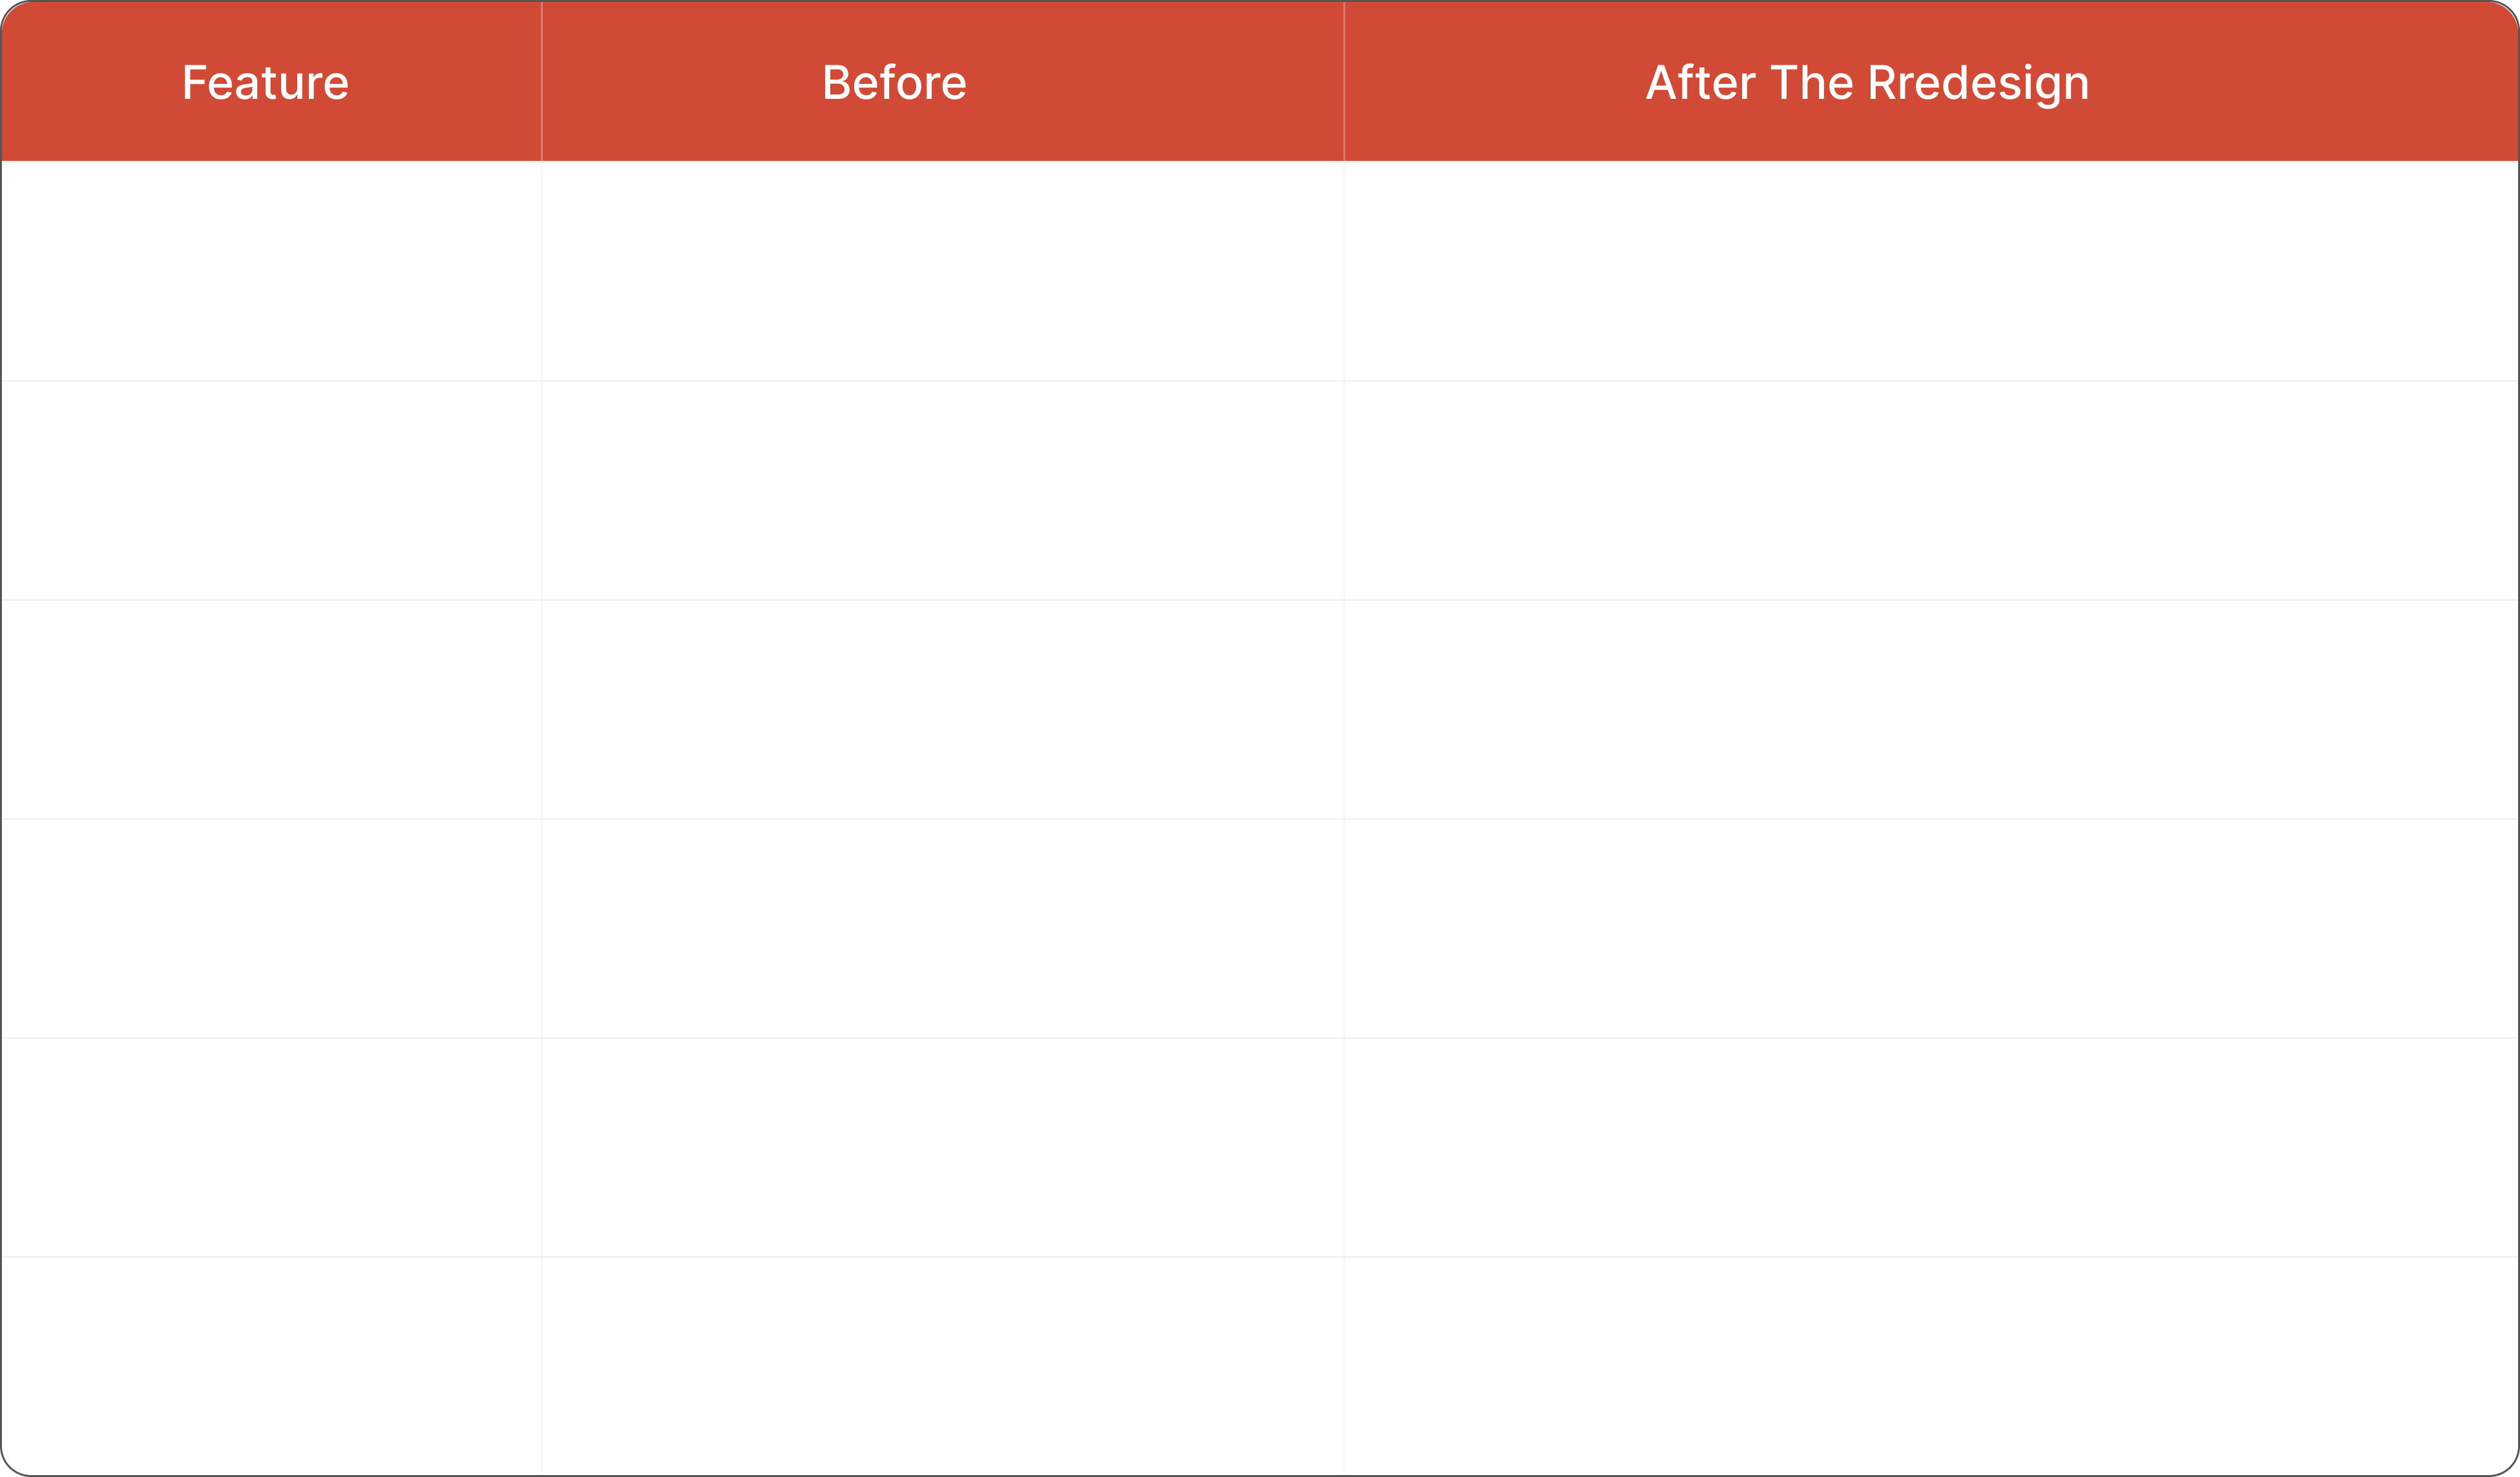
The aim was a candidate sheet where every row could be compared like for like. Here is how ResumeFlow differs from manual screening.
Studied the recruiter’s manual process end to end to see where time was lost and which fields were most often missed or miscopied.
Built the webhook intake and the text and OCR layer to reliably pull content out of varied formats, including embedded links.
Defined the six-field JSON schema, then tuned the prompt against real resumes until the same fields came back every run.
Added required-field checks, date and title normalisation, profile classification, and the thresholds that decide what waits for a human.
Connected the structured output to Google Sheets and ATS destinations so screening could begin the moment a parse finished.
Ran the pipeline against real resume volume, refining prompts and extraction rules until output held up beyond a small sample.



